☆ Bonus
Learning Objectives
- Compare your LoRA to the
peftlibrary's- Learn about variants of GRPO, and libraries like TRL which implement it at scale
- Train your own reward model from human preferences
Extensions of today's exercises
Compare against peft
The peft library is the standard implementation of LoRA (and many other
parameter-efficient fine-tuning methods) for Hugging Face models. Wrap a model with
peft.get_peft_model(model, LoraConfig(r=8, lora_alpha=8, target_modules=list(LORA_TARGET_MODULES))), copy your trained
A and B matrices into its lora_A and lora_B modules (these are nn.Linear layers, so their weights are the
transposes of our A and B), and check that the two models give the same outputs. What
initialization does peft use by default? What other options does LoraConfig have?
Which layers, and what rank?
We adapted every linear layer, following current practice (see the "Which weights should we adapt?" dropdown in the
LoRA section). Try the original paper's choice of just ("q_proj", "v_proj"), or attention-only, or MLP-only, and
compare the trainable parameter counts, memory and results. LoRA Without Regret found that for RL even rank 1 can match
full fine-tuning: does that hold here? With your apply_lora, each of these is a one-line change.
Variants of GRPO
- Try Dr. GRPO (Liu et al., 2025): drop the division by the std in the advantages, and the $\frac{1}{|o_i|}$ length normalization.
- Adjust the training code to handle more than one prompt. You'll need to modify the implementation of GRPO to average over each group separately rather than average all responses, otherwise GRPO may reinforce a completion only because the prompt was easier to answer rather than the model doing a better job. This matters more for RLVR when the reward is computed by checking if the response from the model is correct.
- Allow variable-length completions, stopping at the end-of-text token. You'll need to mask out the tokens after it in the objective and the KL penalty, and think about how to normalize over sequences of different lengths.
- Look into DAPO (Yu et al., 2025), which proposes several more changes, including asymmetric clipping ("clip-higher") and filtering out groups where every sample got the same reward.
- Process supervision: in section 4.1.3 of the GRPO paper, the reward model scores each step of the output rather than only the end. Can you set this up for the period-counting reward?
Hyperparameter sweeps
Find the best possible hyperparameters for your training. Don't just measure the reward: can you use some combination of reward and KL to the reference model to create a better metric? Can you use wandb's built-in Bayesian search methods to more effectively sweep?
Note - don't forget temperature when it comes to hyperparameter tuning. Temperature has an important effect on how the model learns, e.g. if the temperature is too high then the model will produce very high-variance outputs which will have very high KL with the reference distribution, and it'll be more likely to collapse into some incoherent mode. (Also, with temperature $\neq 1$ we're no longer sampling from $\pi_\theta$ itself, so strictly speaking the policy gradient is off-policy. Does this matter in practice?)
Adaptive KL penalty
The KL divergence penalty coefficient can be modified adaptively based on the KL divergence between the current policy and the reference policy. If the KL divergence is outside a predefined target range, we can adjust the penalty coefficient to bring it closer to the target range. Here is an example implementation:
class AdaptiveKLController:
    def __init__(self, init_kl_coef, hparams):
        self.value = init_kl_coef
        self.hparams = hparams

    def update(self, current, n_steps):
        target = self.hparams.target
        proportional_error = np.clip(current / target - 1, -0.2, 0.2)
        mult = 1 + proportional_error * n_steps / self.hparams.horizon
        self.value *= mult
TRL
We've been building RL fine-tuning from the ground up, but there are libraries which abstract away many of the
low-level details. The best-known is TRL (Transformer Reinforcement
Learning), which has a GRPOTrainer that works with peft
for LoRA. Read the documentation, and see which techniques it uses that we haven't implemented here (e.g. using
vLLM for fast generation). We've given you a version of our LoRA training run
that uses TRL and peft at the end of this section: can you train the other tasks with it?
Learn a human preference reward model
We've been working with a pre-supplied reward function, but you can try and train your own!
We'll give some brief points of guidance here, for the task of training a reward function on the summarization task. Note that these instructions have been provided externally, so they've not yet been tested and might not work particularly well.
- Get a supervised baseline
- Here is a link to download the dataset for the TL;DR challenge containing posts from the Reddit corpus. Each post contains keys
contentandsummarywhich are the original post and the human-written summary respectively. - You should throw out all summaries shorter than 24 tokens or longer than 48 tokens (to diminish the effects of length on quality); and choose a random subset of ~100k summaries to train on.
- Run training to maximize the log-likelihood of these summaries.
- Here is a link to download the dataset for the TL;DR challenge containing posts from the Reddit corpus. Each post contains keys
- Get reward model by training supervised baseline on human feedback
- Download comparison data with the code
azcopy copy "https://openaipublic.blob.core.windows.net/summarize-from-feedback/dataset/*" . --recursive - Add a randomly-initialized reward head (a linear layer mapping the final hidden state to a scalar) on top of your model.
- Train your model (starting with base model given by supervised baseline weights, and reward head randomly initialized) to minimize
loss = -log_sigmoid(reward_model(summary_0) - reward_model(summary_1)), wheresummary_0is preferred by a human labeler (this data should be in the comparison data you downloaded).
- Download comparison data with the code
- Fine-tune the supervised baseline using GRPO with your reward model.
Interp on RL fine-tuned models
In this blog post, Curt Tigges walks through an example of how we can use mech interp to analyze a model which has been finetuned with a sentiment based reward function. Can you do something similar with your models? LoRA makes some questions easier to ask: since the update to each weight matrix is low-rank, you can look directly at the directions $A$ reads from and $B$ writes to.
Suggested paper replications
As well as the papers in this section, you might be interested in browsing this GitHub repo, which contains links to a large number of RLHF-related papers.
Deep Reinforcement Learning from Human Preferences
This was the seminal paper in RLHF. They applied it to the domain of tasks like MuJoCo (which you might already have worked with during your PPO day). Can you set up a reward function and an interface which allows you to choose between two different sets of trajectories, and learn a reward function to maximize?
Some more technical details here - the authors train the reward function at the same time as they train the model. In other words, after a certain number of iterations of (rollout phase, learning phase), they add a third reward model learning phase, where the current policy generates many pairs of trajectories of some fixed timestep and the human rater chooses which one is best. They famously trained the Hopper agent to perform repeated backflips using just 900 queries.
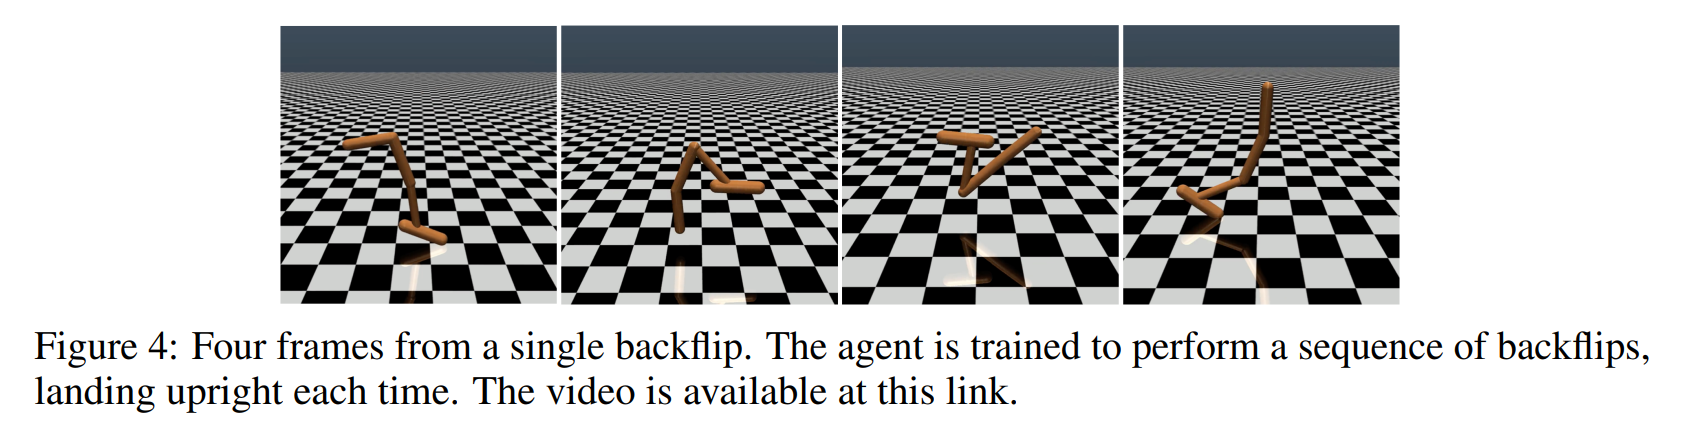
Here is the link mentioned in the image caption of visualisation of some RL environments where the agent was trained with human feedback to elicit some interesting behaviour that would be hard to write explicitly.
Doing this for real: trl and peft
For real RL fine-tuning, use the standard libraries rather than homemade code: TRL's
GRPOTrainer (Hugging Face's reference GRPO implementation)
and peft for LoRA. They also handle many prompts (a group per prompt),
variable-length completions, vLLM generation, multi-GPU training, logging and checkpointing. Below is the same run as
our GRPO_LoRA_Trainer. Differences from ours:
- KL penalty: TRL uses k3 (here), whose gradient is that of the forward KL (see "Estimating the KL
vs. differentiating it"), and defaults to
beta=0.0(no KL penalty or reference model). We setbeta=args.kl_coef. - Loss normalization: the default
loss_type="dapo"(DAPO) averages over all tokens in the batch; we set"grpo"(per sequence first). Identical here, since our completions all have the same length. - Completion lengths: TRL stops at the end-of-text token, rather than always generating
gen_lentokens. peft's LoRA initializes $A$ uniformly (likenn.Linear), and stores it aslora_A, annn.Linearwhose weight is ourAtransposed.- Learning rate decays linearly to zero, not to
final_scaletimes the initial rate.
RUN_TRL_EXAMPLE = False  # set to True to run this example

if RUN_TRL_EXAMPLE:
    # (on Colab: `%pip install trl peft`)
    # ARENA doesn't include all these requirements as it's not core material
    # Try: pip install trl
    from datasets import Dataset
    from peft import LoraConfig
    from trl import GRPOConfig, GRPOTrainer

    trainer = lora_trainer = None  # free the earlier trainers, if there are any
    gc.collect()
    if t.cuda.is_available():
        t.cuda.empty_cache()

    # The same hyperparameters as our LoRA run, which we translate into TRL's names below
    trl_args = GRPO_LoRA_Args(
        reward_fn=partial(reward_fn_sentiment_imdb, direction="neg"),
        prompt=MOVIE_PROMPT,
        num_minibatches=8,
        gen_len=40,
        kl_coef=0.1,
        warmup_steps=0,
        total_phases=10,
    )
    # One of our "phases" is one rollout phase, followed by num_minibatches * batches_per_learning_phase gradient steps
    steps_per_phase = trl_args.num_minibatches * trl_args.batches_per_learning_phase

    grpo_config = GRPOConfig(
        # Rollout phase: one group of `batch_size` completions of the prompt, split into minibatches for learning.
        # (TRL works out the number of completions to generate at once, minibatch_size * num_minibatches, from these)
        num_generations=trl_args.batch_size,
        per_device_train_batch_size=trl_args.minibatch_size,
        steps_per_generation=trl_args.num_minibatches,
        num_iterations=trl_args.batches_per_learning_phase,
        max_steps=trl_args.total_phases * steps_per_phase,
        # Sampling from the model's full distribution, as in our `get_samples`
        max_completion_length=trl_args.gen_len,
        temperature=trl_args.temperature,
        top_k=0,
        top_p=1.0,
        # The GRPO objective
        loss_type="grpo",
        scale_rewards="group",
        epsilon=trl_args.clip_coef,
        beta=trl_args.kl_coef,
        # Optimization
        learning_rate=trl_args.lr,
        max_grad_norm=trl_args.max_grad_norm,
        lr_scheduler_type="linear",
        warmup_steps=trl_args.warmup_steps * steps_per_phase,
        gradient_checkpointing=False,  # trades speed for memory, which we don't need here
        model_init_kwargs={"dtype": trl_args.dtype},
        seed=trl_args.seed,
        # Logging (once per phase), and no checkpoints
        logging_steps=steps_per_phase,
        report_to="wandb" if trl_args.use_wandb else "none",
        save_strategy="no",
        output_dir="grpo_peft_output",
    )
    lora_config = LoraConfig(
        r=trl_args.lora_rank, lora_alpha=trl_args.lora_alpha, target_modules=list(trl_args.target_modules)
    )

    # TRL calls reward functions with the prompts and completions separately, and wants a list of floats back
    def trl_reward_fn(prompts: list[str], completions: list[str], **kwargs) -> list[float]:
        return trl_args.reward_fn([prompt + completion for prompt, completion in zip(prompts, completions)]).tolist()

    trl_trainer = GRPOTrainer(
        model=trl_args.base_model,
        reward_funcs=trl_reward_fn,
        args=grpo_config,
        # We only have one prompt: TRL takes a dataset of prompts, and samples one group of completions for each
        train_dataset=Dataset.from_dict({"prompt": [trl_args.prompt] * trl_args.total_phases}),
        peft_config=lora_config,
    )
    trl_trainer.train()
Faster sampling with vLLM
The same run, sampling with vLLM (use_vllm=True) instead of model.generate, whose time
goes mostly into per-token Python and kernel-launch overhead. On an RTX 5090, per phase (128 completions of 40 tokens):
| Time per phase | |
|---|---|
Our GRPO_LoRA_Trainer |
8.1 s |
TRL + peft |
7.9 s |
TRL + peft + vLLM |
5.9 s |
Sampling is ~8x faster (2.8 s → 0.36 s per phase), but the run is only ~1.35x faster, since with 40-token completions the learning phase dominates. With long completions the gain is bigger (~2.5x in the RLVR material).
vllm_mode:"colocate"runs vLLM in the same process and GPU, with its own copy of the weights, and after each optimizer step TRL merges the adapters into a copy and reloads all the weights into vLLM."server"runs it as a separate process (trl vllm-serve), normally on its own GPUs.- RLVR's alternative (
VLLMEngineinrl_llm_utils.py): the trained model's frozen weights are views of vLLM's, so there's one copy, and only the adapters are pushed to vLLM each step. That needs vLLM created first and the model built on its tensors, which TRL (which creates and syncs its own engine) doesn't allow, so it only works with our own trainer. Here it isn't faster (6.0 s per phase); its payoff is memory, for bigger models and longer completions. - Install vLLM in a separate environment: it pins its own versions of PyTorch and Transformers (
vllm==0.30.0installstorch==2.13.0). - Off-policy: vLLM's kernels give slightly different probabilities to the training model's, which TRL corrects
with importance sampling (
vllm_importance_sampling_correction, on by default).
RUN_TRL_VLLM_EXAMPLE = False  # set to True to run this example

if RUN_TRL_VLLM_EXAMPLE:
    # vLLM isn't in ARENA's requirements, and installing it replaces your versions of torch and transformers with the
    # ones it was built for, so install it into a separate environment: `pip install "trl[vllm]"`. (We tested this with
    # trl 1.14.2 and vllm 0.30.0.)
    from datasets import Dataset
    from peft import LoraConfig
    from trl import GRPOConfig, GRPOTrainer

    trainer = lora_trainer = None  # free the earlier trainers, if there are any
    gc.collect()
    if t.cuda.is_available():
        t.cuda.empty_cache()

    # The same hyperparameters as our LoRA run, which we translate into TRL's names below
    trl_args = GRPO_LoRA_Args(
        reward_fn=partial(reward_fn_sentiment_imdb, direction="neg"),
        prompt=MOVIE_PROMPT,
        num_minibatches=8,
        gen_len=40,
        kl_coef=0.1,
        warmup_steps=0,
        total_phases=10,
    )
    # One of our "phases" is one rollout phase, followed by num_minibatches * batches_per_learning_phase gradient steps
    steps_per_phase = trl_args.num_minibatches * trl_args.batches_per_learning_phase

    grpo_config = GRPOConfig(
        # Rollout phase: one group of `batch_size` completions of the prompt, split into minibatches for learning.
        # (TRL works out the number of completions to generate at once, minibatch_size * num_minibatches, from these)
        num_generations=trl_args.batch_size,
        per_device_train_batch_size=trl_args.minibatch_size,
        steps_per_generation=trl_args.num_minibatches,
        num_iterations=trl_args.batches_per_learning_phase,
        max_steps=trl_args.total_phases * steps_per_phase,
        # Sampling from the model's full distribution, as in our `get_samples`
        max_completion_length=trl_args.gen_len,
        temperature=trl_args.temperature,
        top_k=0,
        top_p=1.0,
        # The GRPO objective
        loss_type="grpo",
        scale_rewards="group",
        epsilon=trl_args.clip_coef,
        beta=trl_args.kl_coef,
        # Optimization
        learning_rate=trl_args.lr,
        max_grad_norm=trl_args.max_grad_norm,
        lr_scheduler_type="linear",
        warmup_steps=trl_args.warmup_steps * steps_per_phase,
        # Sample with vLLM, running in this process on the same GPU ("colocate"), rather than with model.generate
        use_vllm=True,
        vllm_mode="colocate",
        vllm_max_model_length=256,  # the longest prompt + completion we'll need, which saves vLLM some memory
        gradient_checkpointing=False,  # trades speed for memory, which we don't need here
        model_init_kwargs={"dtype": trl_args.dtype},
        seed=trl_args.seed,
        # Logging (once per phase), and no checkpoints
        logging_steps=steps_per_phase,
        report_to="wandb" if trl_args.use_wandb else "none",
        save_strategy="no",
        output_dir="grpo_peft_output",
    )
    lora_config = LoraConfig(
        r=trl_args.lora_rank, lora_alpha=trl_args.lora_alpha, target_modules=list(trl_args.target_modules)
    )

    # TRL calls reward functions with the prompts and completions separately, and wants a list of floats back
    def trl_reward_fn(prompts: list[str], completions: list[str], **kwargs) -> list[float]:
        return trl_args.reward_fn([prompt + completion for prompt, completion in zip(prompts, completions)]).tolist()

    # vLLM 0.30's kernel warmup compiles Triton kernels for other models (Kimi-K3, DeepSeek-V4), which fail with the
    # version of Triton it installs. TRL creates the vLLM engine itself, so we add the option to skip that warmup to its
    # call (kernels then just compile when they're first used)
    import trl.generation.vllm_generation

    trl.generation.vllm_generation.LLM = partial(
        trl.generation.vllm_generation.LLM, kernel_config={"enable_jit_warmup": False}
    )

    # We load the model ourselves (rather than giving GRPOTrainer its name), so that we can empty PyTorch's cache
    # afterwards: when vLLM starts, it measures how much GPU memory is free, and fails if that changes while it does
    model = AutoModelForCausalLM.from_pretrained(trl_args.base_model, dtype=trl_args.dtype).to(device)
    gc.collect()
    t.cuda.empty_cache()

    trl_trainer = GRPOTrainer(
        model=model,
        reward_funcs=trl_reward_fn,
        args=grpo_config,
        # We only have one prompt: TRL takes a dataset of prompts, and samples one group of completions for each
        train_dataset=Dataset.from_dict({"prompt": [trl_args.prompt] * trl_args.total_phases}),
        peft_config=lora_config,
    )
    trl_trainer.train()